 squirrelworks
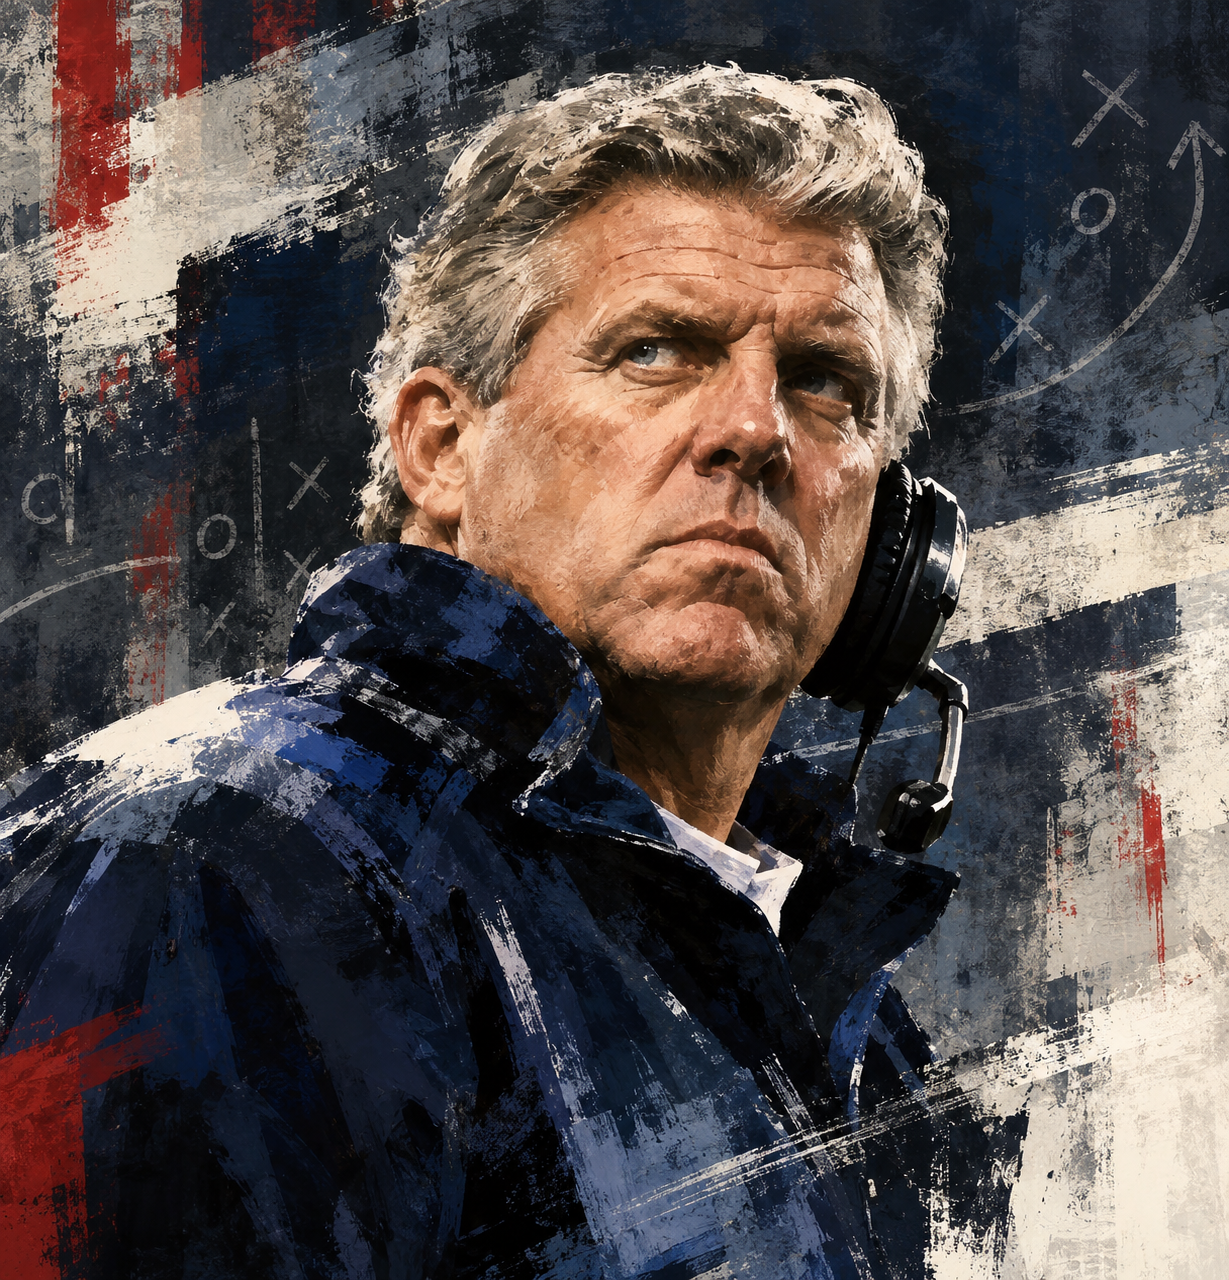
NFL head coach Bill Parcells famously observed that "the best ability is availability." In gridiron football, an elite player sidelined by injury or unreliability yields zero cumulative value. In platform engineering, infrastructure design, and independent technical work, this principle moves from a physical metric to an operational blueprint: raw talent is useless without system stability, routine predictability, and personal discipline.
"You are what your record says you are. And the best ability is availability." — Bill Parcells
In systems administration and platform engineering, uptime is rarely destroyed by cataclysmic events; it decays through unforced human errors, undocumented environments, and heroism culture. A service engineered to "five nines" (99.999% uptime) is built on boring, repeatable routines—not midnight troubleshooting.
A brilliant custom script hacked together at 2:00 AM to patch a failing node represents low availability masquerading as high skill. Automated, version-controlled pipelines keep both the infrastructure and the operator available.
Bespoke, complex configurations spike Mean Time to Recovery (MTTR) when outages occur. Uniform operating system images, strict IaC patterns, and standardized documentation allow instant troubleshooting without context-switching fatigue.
When operating as an independent worker or solo architect, you have no secondary node or backup cluster for failover. You are the hypervisor. Unplanned downtime in your personal routine directly translates to complete system outage.
| Operational Axis | Low-Availability Trait (Erratic Skill) | High-Availability Trait (Routine & Discipline) |
|---|---|---|
| Execution Output | Sporadic sprint marathons followed by exhaustion and burnout. | Fixed, non-negotiable daily deep-work windows. |
| Tooling & Environment | Constantly switching IDEs, stacks, and personal workflows. | Settled, low-friction toolchains tailored for rapid execution. |
| Infrastructure Health | Ignoring sleep, posture, and environmental fatigue. | Strict ergonomics, movement, and recovery cycles. |
Willpower is a finite resource with high volatility. Relying on raw motivation to drive engineering output introduces single points of failure into your daily pipeline. Establishing rigid, deterministic routines functions as systemic redundancy.
By removing decision fatigue around start times, environment provisioning, and task prioritization, execution becomes the default path. When your clients or internal projects rely on your output, delivery on a steady, predictable cadence builds far greater authority than erratic bursts of brilliance.

Eliminate SPOFs: Guard physical health, posture, and recovery; you cannot patch software if the engineer is offline.
Standardize the Pipeline: Reduce workflow variations so deep work requires zero setup time.
Prioritize Consistency: A predictable 8/10 daily output vastly compounds past occasional 10/10 sprees.
Availability is not a passive state—it is an active engineering choice. Whether configuring high-availability Kubernetes control planes or managing independent projects, reliability must be designed into the architecture from day one. Build systems, routines, and habits so disciplined that crisis management becomes an anomaly rather than a standard operating procedure.
Status: Filed under Misc // Systems Philosophy // Case Study
Core Principle: Reliability is a designed feature, not an accidental byproduct.
Explore Related Systems Philosophy & Architecture Modules: